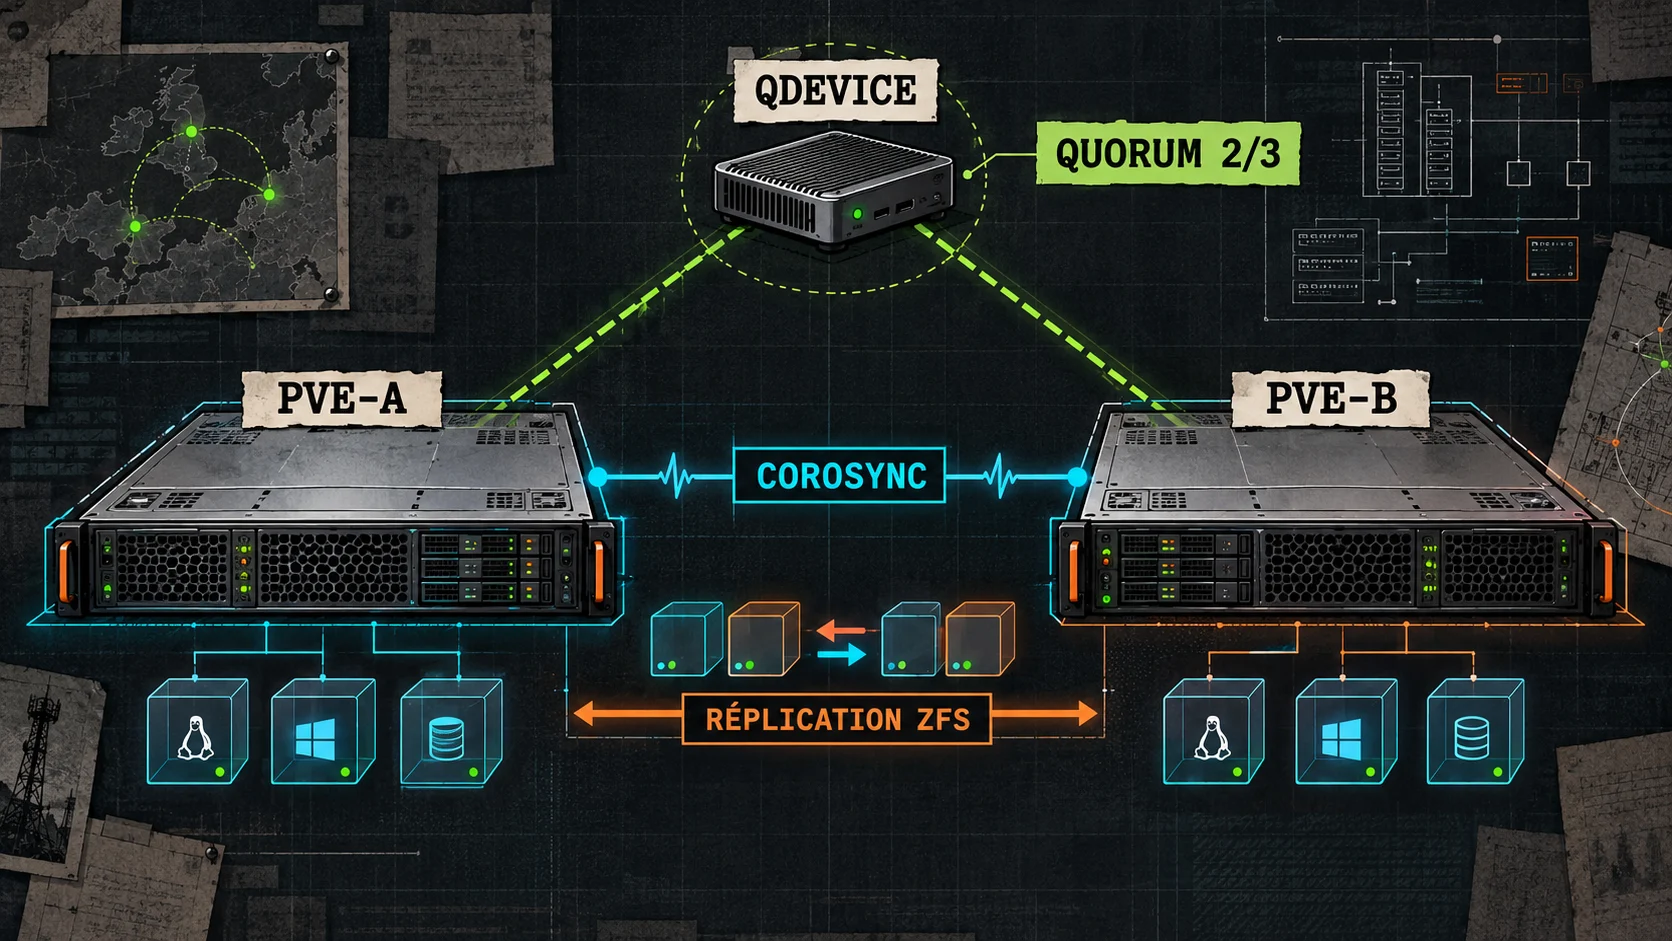
Creating a Two-Node Proxmox Cluster Without Sacrificing the Quorum
Build a two-node Proxmox VE cluster, add a QDevice, migrate the VMs, replicate the ZFS volumes and prepare a safe recovery after a failure.
A two-node Proxmox VE cluster is appealing : two servers appear in the same interface, virtual machines can migrate from one to the other, and ZFS can replicate their disks without shared storage. However, two servers alone do not constitute a safe high-availability platform. When a node disappears, the survivor cannot determine whether it is truly alone or simply separated from its partner by a network failure.
This guide shows how to create the cluster, migrate a VM, configure ZFS replication, and most importantly, add a third vote with a QDevice. This distinction is essential : two nodes facilitate administration and maintenance ; two nodes accompanied by an independent arbiter can make quorum decisions without favoring a split-brain.
What a two-node cluster actually provides
The Proxmox cluster groups multiple hypervisors into a distributed configuration. The pmxcfs file system replicates the settings for the data center, users, firewall, storage, and guests. From the web interface of any member, you can administer the others.
With two nodes, you immediately get :
- a common, multi-master administration interface ;
- cluster-wide unique VM and container identifiers ;
- live or offline migration between hosts ;
- asynchronous replication of local ZFS volumes ;
- distributed backup jobs, permissions, and rules.
On the other hand, the cluster does not automatically create shared storage, does not turn replication into a backup, and does not enable reliable high availability without quorum. HA resources must be configured separately, and their disks must be accessible on the node that takes them over.
Why quorum blocks the surviving node
Corosync normally assigns one vote to each node. In a two-member cluster, the total is two votes, and the majority requires two. If communication is broken, each server only sees one vote. The cluster file system then switches to read-only to prevent both sides from simultaneously modifying the same configuration.
This behavior is not a cluster failure : it is its primary protection against split-brain. Without an arbiter, no server can know whether the other is shut down or still active behind a failing network link.
| Architecture | Votes | Majority | Node failure |
|---|---|---|---|
| 2 nodes alone | 2 | 2 | The survivor loses quorum |
| 2 nodes + QDevice | 3 | 2 | The survivor can receive the arbiter's vote |
| 3 Proxmox nodes | 3 | 2 | Two nodes naturally retain quorum |
The QDevice does not host any VMs and does not store the cluster's disks. It provides an external vote to a single partition of the cluster. A small independent Debian system is sufficient, provided it remains reachable by both nodes. Avoid placing this arbiter in a VM hosted by the cluster it is meant to arbitrate.
Preparing the two servers
Before clicking on " Create Cluster ", check the following points :
- Identical versions : update both hosts and use the same generation of Proxmox VE.
- Unique and resolved names : each host must resolve the name and address of the other, without future modification of the host name.
- Fixed addresses : reserve a stable address for each Corosync link.
- Synchronized time : check NTP on both servers.
- Reliable network : Corosync uses UDP 5405 to 5412, and adding a node requires SSH on TCP 22.
- Empty node to join : it must not contain any VMs or containers.
- Consistent storage : use the same storage identifiers and, for replication, compatible ZFS pools on both hosts.
- Verified backup : export configurations and back up guests before any cluster operation.
A separate Corosync network is not strictly mandatory in a small lab, but it becomes highly recommended as soon as migrations, backups, and storage generate a lot of traffic. If two links are configured, they must take genuinely distinct paths : two VLANs on the same switch do not protect against a failure of that switch.
1. Create the cluster on the first node
Log in to the web interface of the first server, then open Datacenter → Cluster → Create Cluster. Choose a short name without spaces, for example Prox, and select the network address used by Corosync.

The same operation can be performed from the shell of the first node :
pvecm create Prox --link0 192.168.68.31Then check the cluster status :
pvecm status
pvecm nodes
At this stage, only one node is a member, and the interface offers the Join Information button. Copy the provided block : it contains the address of the existing member, its certificate fingerprint, and the information required for addition.
2. Join the cluster from the second node
Open the web interface of the second server, then Datacenter → Cluster → Join Cluster. Paste the copied information, enter the root password of the first node, and select the local address of the Corosync link.

192.168.68.31 and the second node presents its local link 192.168.68.32.From the shell of the second node, the equivalent is :
pvecm add 192.168.68.31 --link0 192.168.68.32The web session of the second node normally interrupts during integration : its certificate is replaced by a certificate signed by the cluster authority. Wait a few moments, fully reload the page, and log back in with the cluster credentials.
Both nodes should now appear under the same data center. Check pvecm status again. Without a QDevice, the cluster is operational when both hosts communicate, but it will lose quorum as soon as one of them or the link connecting them disappears.
3. Add the third vote with QDevice
Prepare a small independent machine running Debian or a distribution offering corosync-qnetd. It can be low-powered : its role is solely to arbitrate. Preferably place it on a separate power supply and network path from the two hypervisors.
On the arbiter :
apt update
apt install corosync-qnetd
On both Proxmox nodes :
apt update
apt install corosync-qdevice
Then, from a cluster member, configure the arbiter :
pvecm qdevice setup 192.168.68.50Replace the address with that of your arbiter. The command prepares the certificates and registers the external vote. A new run of pvecm status should show three votes in total and a quorum set to two.
4. Migrate a virtual machine
Right-click the VM, choose Migrate, and then select the target node. Live migration keeps the VM running during the transfer of its memory and, when disks are local, its volumes.

local-zfs disks must be copied to the target node.The duration depends on storage and network :
- Shared storage : the disks remain in place, and only the VM state, modified memory, and virtual devices need to switch over.
- Local storage : Proxmox copies the volumes to the target storage, which can transfer several hundred gigabytes.
- Already replicated ZFS : the majority of the blocks already exist on the target, and only changes since the last replication need to be sent.
Network bridges must have the same names on both hosts. For different processors, choose a virtual CPU model compatible with both machines rather than host. The QEMU Guest Agent is recommended for clean operations within the guest, but it is not an absolute requirement for live migration.
5. Replicate ZFS disks
Proxmox replication works with local ZFS volumes. It creates snapshots, sends an initial full copy, and then transfers only the modified blocks. In the relevant VM, open Replication → Add, choose the target node, and define the schedule.

The first synchronization is the longest. Subsequent ones are incremental, and their frequency does not automatically multiply the occupied space by as many full copies. A bandwidth limit can prevent replication from choking user traffic.
After a migration to the replication node, Proxmox automatically reverses the direction of the job. The new source machine then sends its changes back to the old host. Regularly check the job status and log : a configured but failing replication provides no protection.
What happens when a node fails ?
The answer depends on three elements : quorum, disk availability, and HA activation.
- Two nodes with QDevice and HA : the survivor can retain quorum and restart HA resources whose volumes are available.
- Two nodes with QDevice, without HA : the cluster remains editable, but restarting the VM is still a manual operation.
- Two nodes without QDevice : the survivor loses quorum, and
/etc/pvebecomes practically uneditable. - Replicated ZFS : the disk available on the target corresponds to the last successful synchronization ; subsequent writes are lost.
Before any manual recovery, ensure that the failing node is actually powered off or isolated from the cluster's storage and network. This fencing prevents two instances of the same VM from accessing the same data.
Use pvecm expected 1 only in emergencies
Without a QDevice, it is possible to temporarily lower the expected number of votes on the sole survivor :
pvecm status
pvecm expected 1
This command is for emergency recovery, not for daily operation. Run it only if the second node is confirmed to be shut down and cannot reconnect during the intervention. Do the bare minimum, then repair the normal quorum, and never bring both sides back online with divergent states.
For a non-HA managed VM whose disks are all already accessible from the survivor, the Proxmox documentation allows moving its configuration file to the active node's directory. Example for VM 100 :
mv /etc/pve/nodes/pve-b/qemu-server/100.conf \
   /etc/pve/nodes/pve-a/qemu-server/
Do not use this command if the disks are not present and consistent on pve-a. It changes the logical owner of the configuration ; it does not copy the data. For a HA-managed guest, let the HA manager and the fencing mechanism perform the recovery.
Why you should not give a node two permanent votes
Modifying /etc/pve/corosync.conf to assign two votes to a " primary " host seems to resolve the lockup when the other server is stopped. In reality, this asymmetry turns the first node into an arbiter of its own partition and weakens the cluster's security model.
If the network goes down while both machines are running, the privileged node can continue writing while the other sees a different situation. A storage error, an unexpected boot, or a configuration restoration can then create contradictory states. The QDevice exists precisely to entrust the third vote to an independent system capable of electing only one side.
Validation plan before production
- Check
pvecm statusand the presence of the three votes with QDevice. - Test a live migration in both directions.
- Create a short replication, check its log, then migrate the VM to verify the direction reversal.
- Cleanly shut down a test node and confirm that the survivor remains quorate.
- Test the loss of the QDevice alone : the two hypervisors combined must continue to operate.
- Check the boot order, shutdown delays, and QEMU Guest Agent of important VMs.
- Restore a backup to a test identifier before considering the plan validated.
- Document the addresses, Corosync links, storage, dependencies, and fencing procedures.
Conclusion
A two-node Proxmox cluster is very useful for centralizing administration, moving VMs, and replicating ZFS volumes. However, these functions should not be confused with full high availability. Without a third vote, the loss of a member intentionally immobilizes the survivor to protect consistency.
The right compact architecture is therefore clear : two equivalent Proxmox nodes, a reliable Corosync network, consistent storage, an independent QDevice, monitored replications, and separate backups. Availability comes from the combination of these mechanisms, not simply from the fact that two servers appear under the same data center.
Technical references
Read next


About the author
 Jeremy Kraft runs the infrastructure and the self-hosted services of the IBCSC. These guides describe configurations that were actually deployed and re-checked before publication.
Discussion
Comments
No comment yet. Feel free to open the discussion with a question or your own experience.